 RiskVoidSecurity Agent Kit
The AI security agent you can put in front of a client.
It reviews code and tests web apps, APIs and AI apps with 45+ real security tools. A firewall enforces the scope, you approve the risky steps, and it writes the report.
For authorised work only: systems you own or have written permission to test.
A real 30-minute run on the practice lab, sped up to under a minute.
 Kali Linux
- OpenHands
- LiteLLM
 Model Context Protocol
 SearXNG
 Docker
 OWASPWSTG · ASVS · API Top 10 · LLM Top 10
- PTES
- MITRE ATLAS
- SLSA · OpenSSF
Built for work you answer for.
Other agents lead with autonomy. This one lets you show what it touched, who allowed it, and where the client's code went.
Scope by firewall.
A tool can't reach a host you didn't list, even if the model tries.
- Passive, active and intrusive tiers
- Single-use approvals
- One command halts everything
Code stays with you.
Only the worker model reads source and raw tool output. You pick where it runs.
- Your GPU, a rented one, or hosted
- Zero-data-retention providers only
- Fully offline mode
Evidence you can defend.
Every command is logged out of the agent's reach. Every artefact is hashed.
- SHA-256 on every artefact
- A person approves the report
- Sealed engagement archive
For people who sign the report.
Faster engagements.
It runs the checks and drafts the report in your branding. You approve the risky steps.
Your first engagementCode review in one run.
Source, dependencies and secrets, with SARIF out. The repo never leaves your network.
Working with the agentTest your own agent.
Prompt-injection probes and an MCP server audit, mapped to the OWASP LLM Top 10.
The practice labWhat it can test.
Describe the job in plain language. The agent plans, runs the tools and writes it up.
Vulnerability intel
CVE lookups from CISA KEV, EPSS, NVD and OSV.
Findings database
Triage, dedupe and severity.
Retests
Before and after evidence on the fixed build.
Not covered yet: Active Directory, cloud, Kubernetes, mobile. All 45+ tools and their tiers
Controls outside the model.
Enforced by the network and the tool server. The agent can't talk its way past them or approve its own requests.
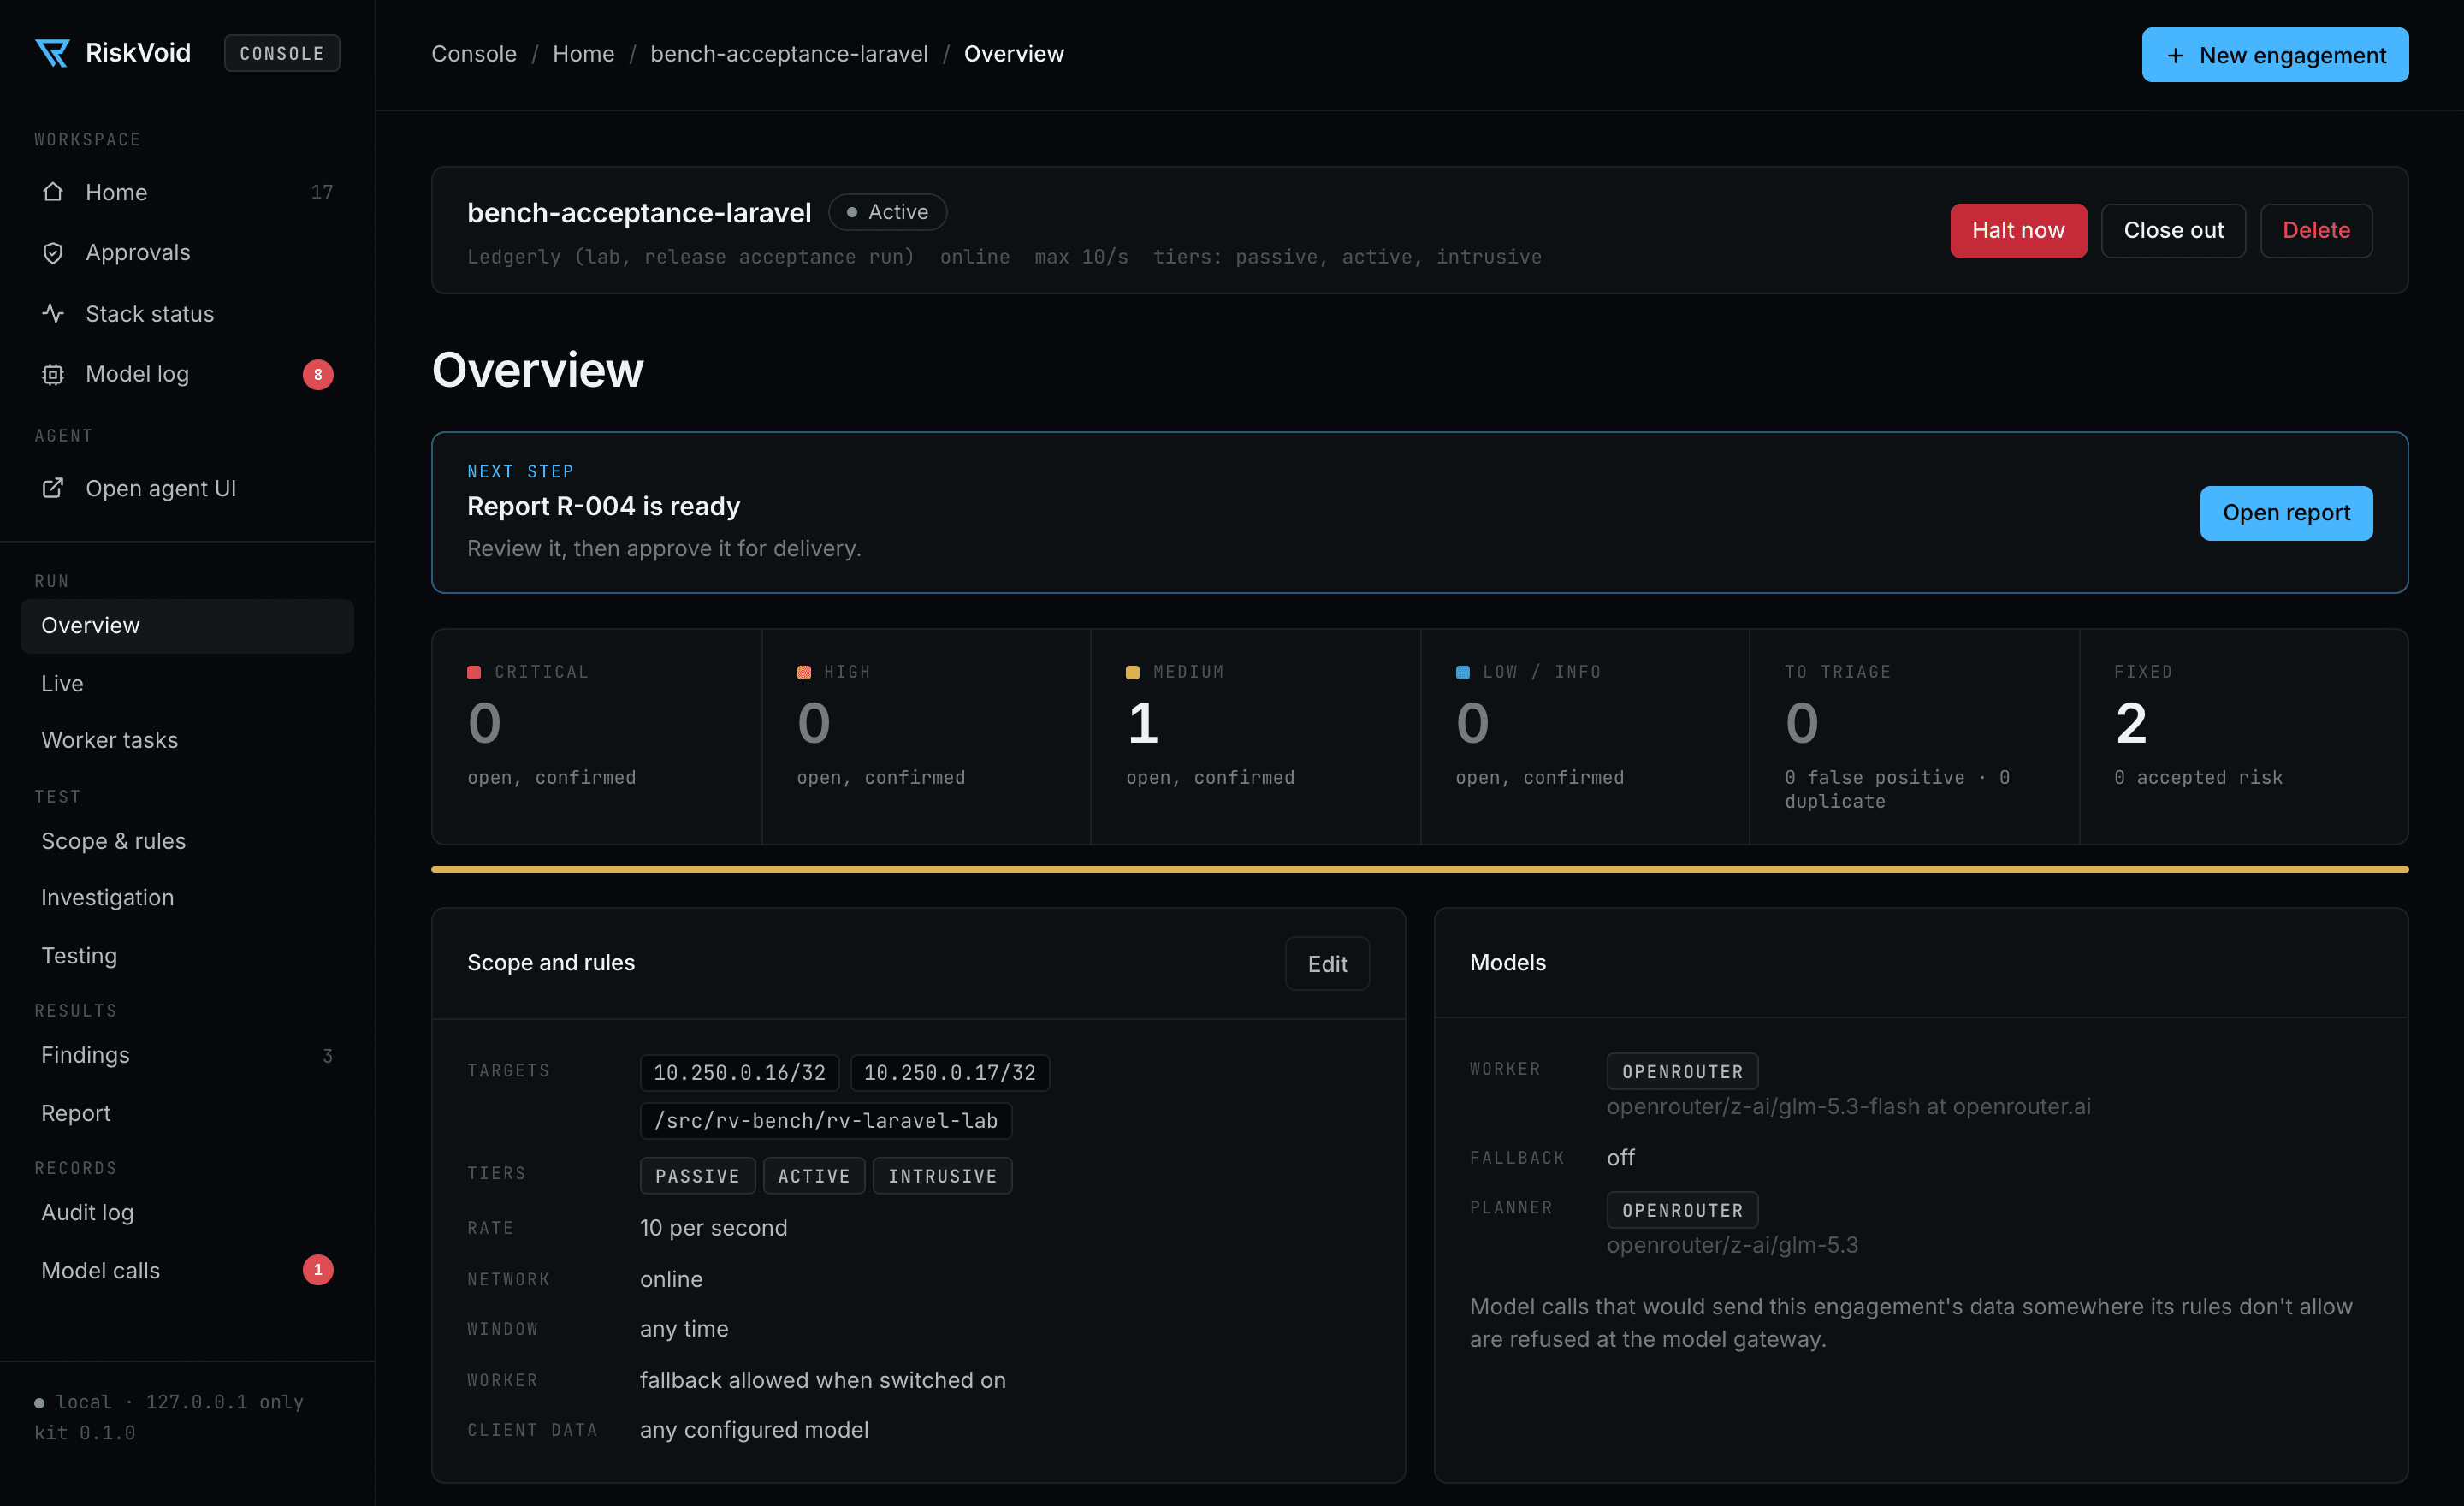
Scope firewall
Only the targets you listed are reachable.
Tiers
Passive, active or intrusive. You choose what's allowed.
Approvals
Intrusive commands wait for your yes, once each.
Rate limits
Scanners are capped at your maximum rate.
Halt
One command kills everything running.
Audit log
Every command, refusal and approval is recorded.
Contained agent
No direct internet, and it can't widen its scope.
Strict mode
Optional: scripts need approval too.
Each control has a test: see the regression matrix. Known limitations are in SECURITY.md.
You choose where code is read.
Only the worker model reads source code. Pick where it runs.
Runs the tools, reads the code
Sees client code and tool output.
Plans, triages, writes
Sees redacted summaries and findings.
Evidence, audit log, reports
The whole engagement folder.
./rvkit worker openrouterTwo models, one sandbox.
Everything runs in Docker on your computer.
Agent UI
Where you describe the job.
Planner
Plans, triages and writes.
Worker
Runs the tools, reads the code.
Kali sandbox
45+ tools, isolated per engagement.
firewall
Target
Only what you authorised.
Console
Approve, halt, triage, report.
Findings & report
HTML, Word, PDF, Excel, SARIF.
Model gateway
Spend cap and fallbacks.
Audit log
Plus hashed evidence.
A full agent harness.
Not a prompt wrapped around a shell. Most of the kit is the machinery around the model.
Focused tasks
The worker gets one goal and returns a redacted summary. Raw output never reaches the planner.
Scope compiled into policy
SCOPE.md and RULES.md become versioned policy. A line the kit can't enforce is an error.
Exact-action approvals
Bound to a digest of the command, its inputs and the policy revision. Used once.
A sandbox per command
Own namespaces, an unprivileged user, and only the credentials the command names.
Data routes enforced
An offline engagement can't reach a cloud model, whatever the conversation asks.
Survives a restart
Tasks resume from a checkpoint. An in-flight write is flagged, not repeated.
Refusals handled
A refused or empty reply is retried or answered by a fallback model.
Verified findings only
A candidate is confirmed only when the planner states how it was verified.
Its own test suite
Fifteen integration suites run nightly, with a regression test per control.
Console and report.
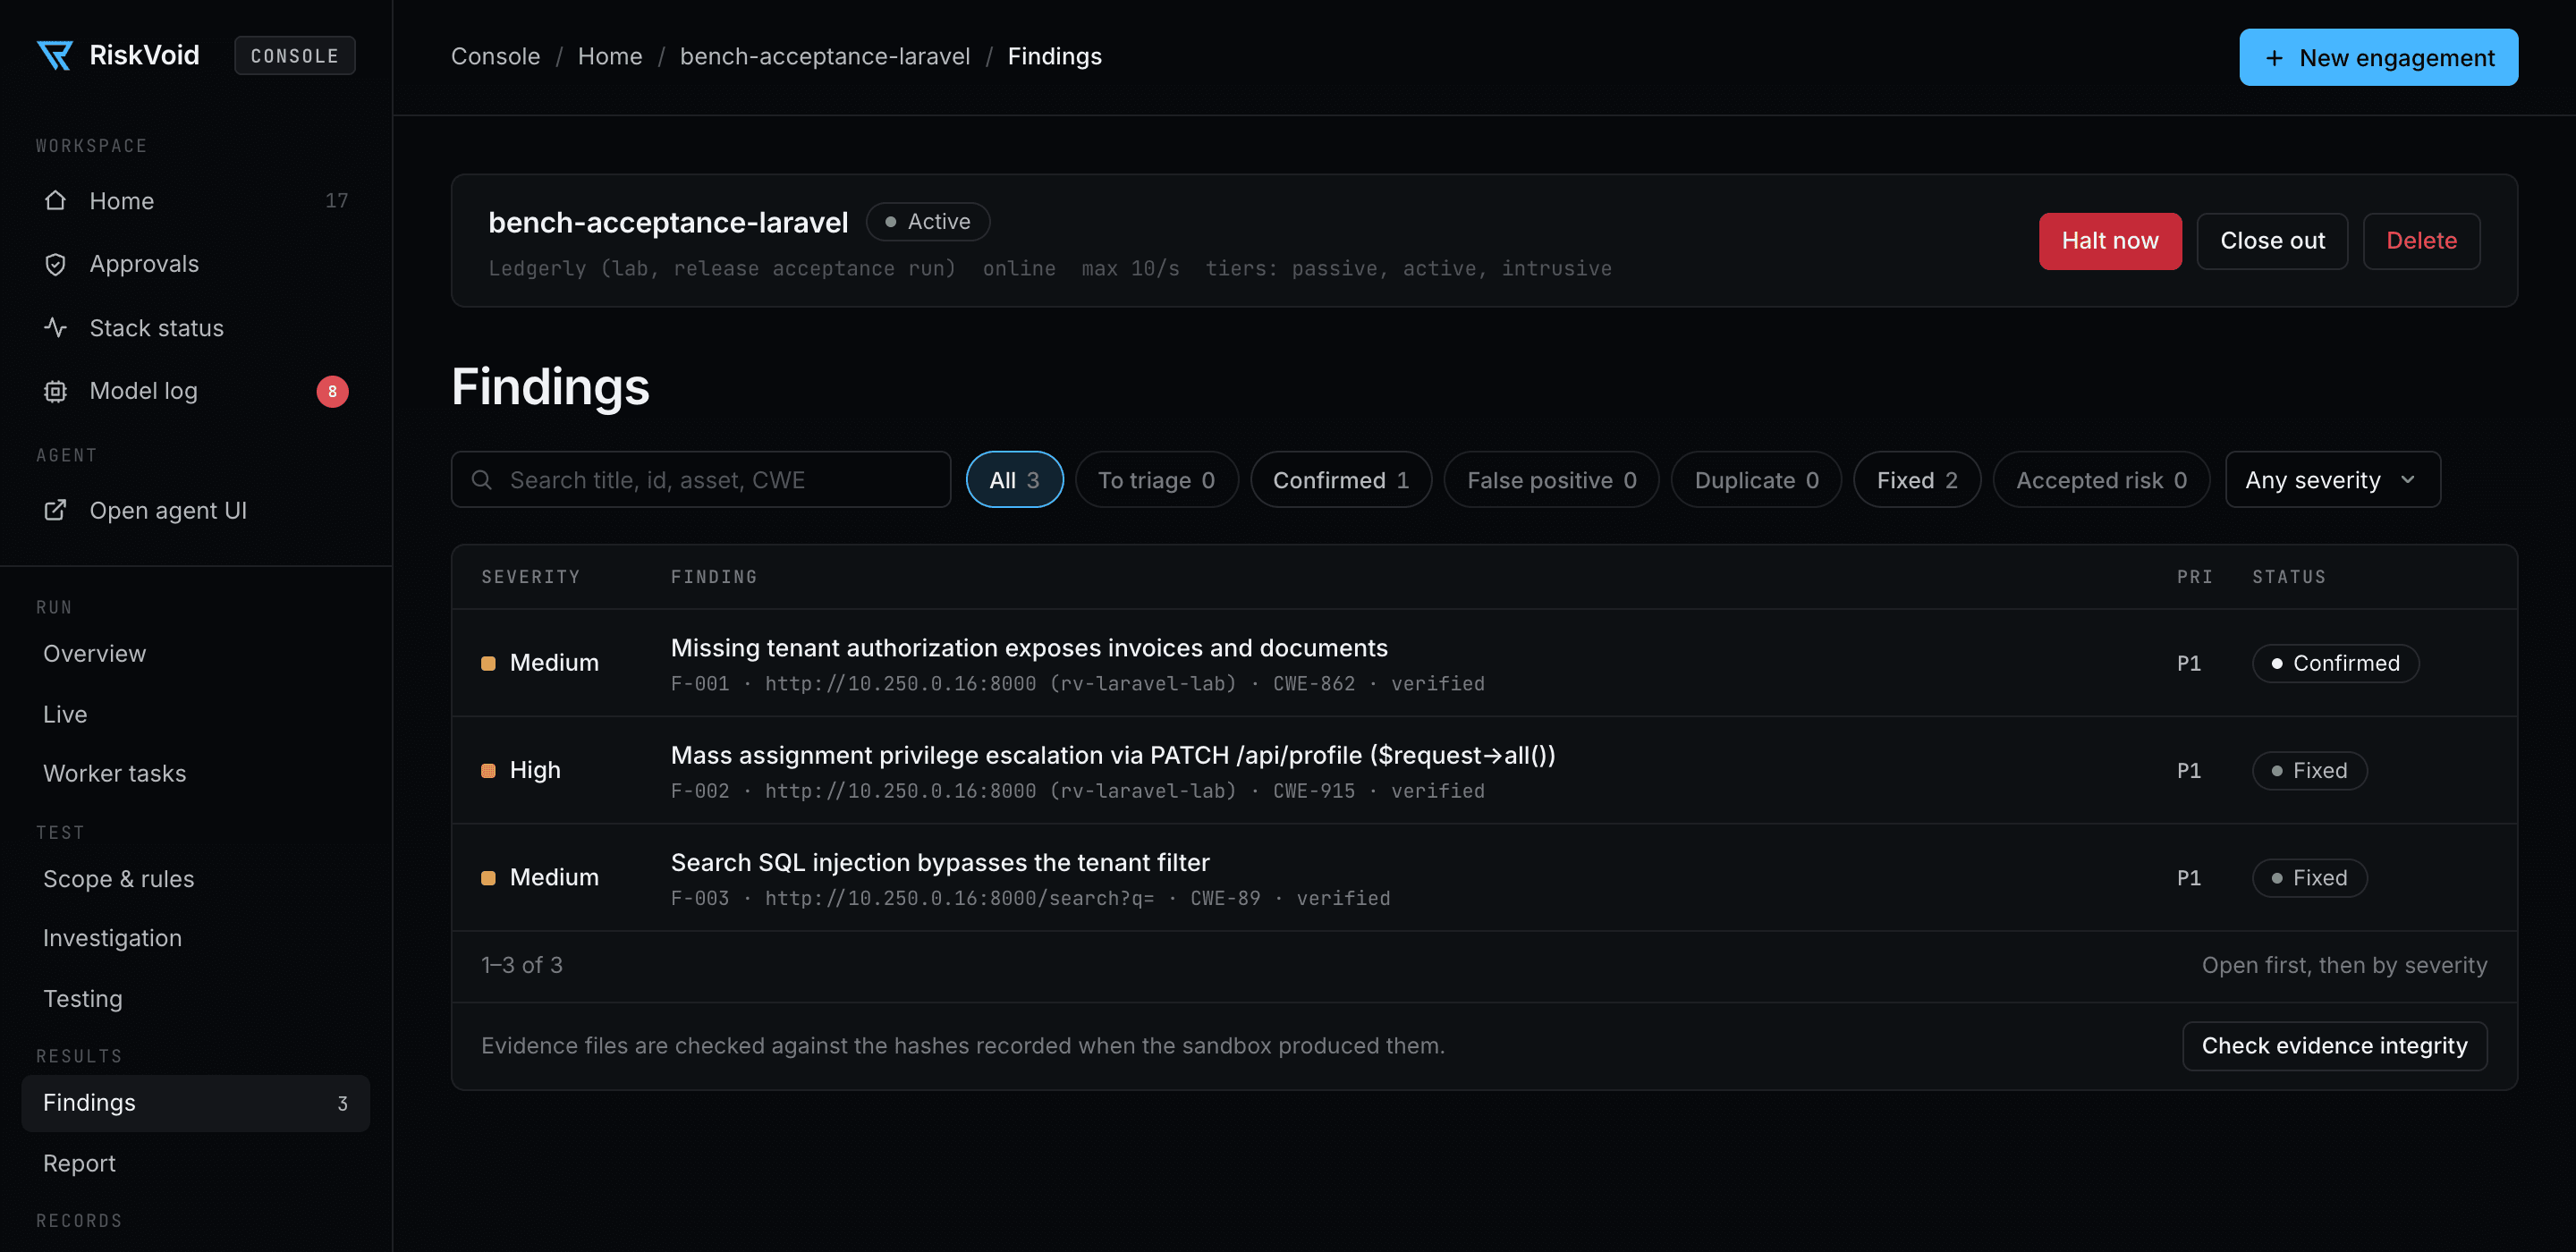
The RiskVoid Console
Findings from the same lab run as the sample reports. Runs on 127.0.0.1 only.
The deliverable
A report in RiskVoid branding or your own, approved by a person before delivery.
Scored on evidence.
A finding counts only with the right place and the required proof. No run flagged a clean control.
| Benchmark | Found | With evidence | Precision | Cost |
|---|---|---|---|---|
| Flask service (source) | 6 of 6 | 6 of 6 | 0.67 | $1.16 |
| Express API (source) | 9 of 9 | 6 of 9 | 0.50 | $1.48 |
| LLM app and MCP server | 8 of 10 | 6 of 10 | 1.00 | $1.10 |
| DVWA | 8 of 8 | 8 of 8 | 0.40 | $3.13 |
| OWASP Juice Shop | 3 of 7 | 2 of 7 | 0.25 | $1.85 |
| DVGA (GraphQL) | 3 of 9 | 3 of 9 | 0.75 | $1.01 |
| VAmPI (REST) | 3 of 9 | 2 of 9 | 1.00 | $0.52 |
| Laravel lab, unattended | 1 of 6 | 1 of 6 | 1.00 | $1.10 |
| Laravel lab, with a person approving | 3 of 6 | 3 of 6 | 1.00 | $1.44 |
2026-11-10. One capped run each, GPT-6.1 planner and DeepSeek worker. Single runs vary.
Source review is the strongest part.
Every seeded issue found on both code targets.
Black-box testing is uneven.
DVWA complete; other labs a third to a half.
A person in the loop helps.
Approvals took the Laravel run from one finding to three.
Run them yourself: ./rvkit bench <name>. Full results and method
How it compares.
For a CTF or your own lab, a more autonomous agent may suit you better. This one is for work someone will audit.
| Capability | Security Agent Kit | Strix | Shannon | PentAGI | HexStrike AI |
|---|---|---|---|---|---|
| Scope enforced by the network | Yes, per engagement | Not mentioned | Rules-of-engagement config | Not mentioned | Not built in |
| Human approval for intrusive steps | Yes, single-use | Not mentioned | Not mentioned | Not mentioned | Not built in |
| Audit log | Yes, out of the agent's reach | Not mentioned | In Pro | Not mentioned | Not built in |
| Hashed evidence | SHA-256 on every artefact | Not mentioned | Not mentioned | Not mentioned | Not mentioned |
| Reports in the free version | HTML, Word, PDF, Excel, SARIF | Local viewer | PDF, Markdown, JSON, SARIF | Markdown, PDF | Vulnerability cards |
| Proves exploits automatically | Not yet, next on the roadmap | Yes | Yes | Not mentioned | Not mentioned |
| Licence | Apache-2.0, nothing gated | Apache-2.0, paid editions | AGPL-3.0, Pro edition | MIT, Enterprise edition | MIT |
From each project's README, 2026-11-08. Others are ahead on exploit validation, easy installs and autonomy. Full comparison with sources
Just ask your coding agent.
Open the kit folder in your coding agent and ask in plain words. The repo ships its instructions and safety rules.
 Claude Code
 Cursor
 GitHub Copilot
 Gemini CLI
- Codex
- Create an engagement for Acme Ltd with scope app.acme.com.
- What's waiting for my approval?
- Build the report for acme-2026-11 and close it out.
$ cd Security-Agent-Kit && claude

/rv-setup   # installs, starts everything, runs the checks
/rv-start   # starts the worker on a Colab GPU
/rv-stop    # releases the GPU

# any other agent:
> Set up the RiskVoid kit. Follow AGENT_PLAYBOOK.md.
Up in ten minutes.
Setup asks four questions and starts the stack. Then practise on the isolated lab.
 macOS
 Linux
- Docker
 OpenRouter
 Colab
 Ollama
- Machine
- Mac or Linux with Docker. 16 GB RAM, 25 GB disk.
- Key
- An OpenRouter key. A few dollars covers many runs.
- Windows
- Not supported yet.
$ git clone https://github.com/RiskVoid/Security-Agent-Kit.git
$ cd Security-Agent-Kit
$ ./rvkit setup

$ ./rvkit doctor       # checks everything, says what to fix
$ ./rvkit quickstart   # practice engagement in the lab
$ ./rvkit console      # approvals, live view, findings, report
Common questions.
Do I need a GPU?01
What does it cost to run?02
Does client code leave my machine?03
Does it replace a penetration tester?04
Can I put my own brand on the report?05
Is the licence going to change?06
Can I use it in CI?07
Is it legal to use?08
How do I report a security issue in the kit?09
Try it on the lab first.
An isolated practice lab is included. One guided run takes about 20 minutes.